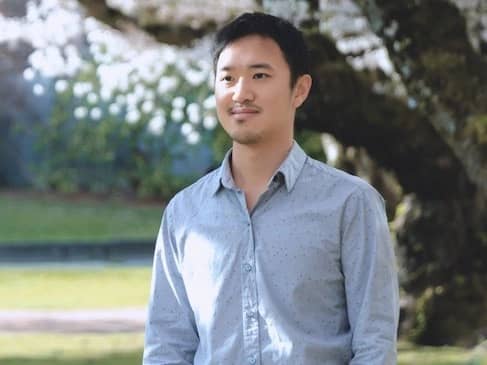
Yuanzhi Li
Yuanzhi Li is a computer scientist and assistant professor of computer science at Carnegie Mellon University, whose research focuses on machine learning theory and large language models. His work spans deep learning, optimization, and the mechanisms that govern the capabilities of large language models, and he has been a collaborator on Microsoft's Phi series of small language models as a co-author of several technical reports. He is also a primary author of the multi-part "Physics of Language Models" series, which studies how language models store and manipulate knowledge.[3][8][9][10]
Education
Yuanzhi Li attended Princeton University, where he earned a Ph.D. in computer science in 2018. His doctoral dissertation was titled "On the ability of gradient descent to learn neural networks," which investigated the theoretical principles governing the training of neural networks through gradient-based optimization techniques.[1][3]
Career
Li completed a postdoctoral appointment at Stanford University after earning his Ph.D., working on theoretical aspects of modern machine learning. He joined Carnegie Mellon University as an assistant professor of computer science in 2019, focusing on the theory and practice of deep learning, optimization, and large language models. While at Carnegie Mellon, he has been a central collaborator on the Microsoft Phi family of small language models, co-authoring technical reports on models including phi-1.5, Phi-3, and Phi-4 that emphasize data quality and efficient scaling, and he has co-led the multi-part "Physics of Language Models" research program on how language models store, extract, and scale factual knowledge.
In July 2025, media reports described Meta Platforms as recruiting Yuanzhi Li to contribute to its newly created Meta Superintelligence Labs, an effort aimed at building advanced AI systems, although these reports did not specify his formal title or detailed responsibilities.[3][8][9][10][2][4]
Research and Publications
Li's research covers a broad spectrum of topics within machine learning and theoretical computer science. His work often seeks to answer fundamental questions about the mechanisms, capabilities, and limitations of deep learning models, with a focus on optimization dynamics, generalization, feature learning, and the behavior of large language models. He has published numerous papers in prominent conferences and journals, including NeurIPS, ICML, ICLR, COLT, FOCS, and STOC, and is a major contributor to the multi-part "Physics of Language Models" program, which analyzes how language models represent, retrieve, and scale factual knowledge.[1][5][9][10]
Deep Learning Theory
A significant portion of Li's research is dedicated to the theoretical properties of neural networks. He has co-authored foundational work on the convergence and behavior of optimization algorithms such as Stochastic Gradient Descent (SGD) and Adam, especially within the context of over-parameterized models that are common in modern deep learning. His research in this area analyzes the implicit bias of optimization algorithms, the role of initialization and learning rates in determining training outcomes, and mechanisms underlying adversarial robustness and self-supervised learning. Representative publications that reflect these contributions include "A Convergence Theory for Deep Learning via Over-Parameterization," "Backward Feature Correction: How Deep Learning Performs Deep (Hierarchical) Learning," and "Towards Explaining the Regularization Effect of Initial Large Learning Rate in Training Neural Networks."[1][5]
Large Language Models
In recent years, Li has focused on the principles and emergent abilities of large language models (LLMs), including their reasoning capabilities, knowledge representation, and scaling behavior. He was a co-author of the 2023 paper "Sparks of Artificial General Intelligence: Early experiments with GPT-4,"[11] which analyzed the advanced reasoning and problem-solving capabilities of the model and argued that such systems display a broad range of cognitive skills. He is also a co-author of the "Physics of Language Models" series of papers, which aims to establish a theoretical framework for understanding how LLMs store and organize factual knowledge, how that knowledge can be extracted and manipulated, and how knowledge capacity scales with model size, architecture, and training procedures.[9][10]
Li co-authored the paper "LoRA: Low-Rank Adaptation of Large Language Models."[12] This work introduced a parameter-efficient fine-tuning technique that reduces the computational cost of adapting large pre-trained models to specific downstream tasks and has become a widely adopted method in the practical application of LLMs.[1][5][6]
Microsoft Phi Models
Li has been a key collaborator on the development of the Phi family of small language models with researchers at Microsoft. He is listed as a co-author on the technical reports for "Textbooks Are All You Need" (which introduced the concepts behind Phi-1), "Textbooks Are All You Need II: phi-1.5 technical report," the "Phi-3 Technical Report," and the "Phi-4 Technical Report." This research demonstrated that models trained on high-quality, "textbook-like" data could achieve performance on reasoning and language understanding benchmarks that was comparable to, or even exceeded, that of much larger models. The work challenged the view that model capability is primarily a function of scale (i.e., parameter count) and highlighted the importance of training data quality and curation.
In addition to his work on deep learning theory and LLMs, Li has made contributions to other areas of machine learning, including reinforcement learning, generative modeling, and convex optimization. His research in these domains includes theoretical analyses of Generative Adversarial Networks (GANs), the development of theory for diffusion models, and the design of efficient bandit algorithms. Representative papers from these areas include "Sampling is as easy as learning the score: theory for diffusion models with minimal data assumptions" and "Settling the Horizon-Dependence of Sample Complexity in Reinforcement Learning."[1][5][8]
Interviews
Discussion on the Tiny Stories Dataset
On June 6, 2023, the Cognitive Revolution podcast featured a discussion between Nathan Labenz, Ronen Eldan, and Yuanzhi Li of Microsoft Research regarding the Tiny Stories project. Li explained that the project involves a synthetic dataset of approximately 1.5 million children’s stories generated using GPT-4 and GPT-3.5. The dataset employs a restricted vocabulary of around 2,000 simple words and was designed to enable the training of small-scale language models ranging from 1 million to 33 million parameters, representing about 2% of GPT-2’s size.
According to Li, the project provides a framework for examining the development of core language abilities, such as grammar, factual recall, and basic logical operations, within smaller models. He stated that model depth is associated with the complexity of reasoning processes, while model width is linked to memory capacity for factual information. The models’ attention mechanisms were described as exhibiting two main patterns: “distance heads,” which focus on positional relationships between tokens, and “semantic heads,” which prioritize content relevance.
Li also noted that reasoning tasks are relatively uncommon in large-scale natural language datasets and may compete with factual memorization for model capacity. The Tiny Stories dataset, he explained, can be used to apply a form of curriculum learning in which linguistic and reasoning skills are introduced in a structured manner. In terms of interpretability, Li indicated that smaller models tend to allow clearer identification of neuron and attention head functions, whereas larger models distribute functions across more parameters, making them harder to analyze. He compared the practical control of models to horseback riding, where effective use does not require a complete understanding of internal processes.
The discussion outlined how the Tiny Stories framework can be applied to study the behavior, reasoning capabilities, and interpretability of language models under computationally limited conditions.[7]